Quick Answer
Every developer eventually faces the dreaded moment when they commit code that breaks the build, introduces an infuriating bug, or includes files that should never have been tracked in version control. When this happens, mastering Git's history-rewriting capabilities becomes essential for maintaining project integrity. Two primary commands serve this exact purpose: git reset and git revert. While both are designed to undo changes, they approach the problem through fundamentally different philosophies. Understanding when to deploy git reset versus git revert is a critical milestone in a programmer's version control proficiency. Choosing the wrong tool can accidentally erase important work, disrupt your teammates' workflows, or leave your repository in a tangled, unresolvable state. This comprehensive technical guide explores the inner mechanics of both commands, analyzing their impact on local and shared histories, examining safety considerations, and providing practical scenarios to help you navigate version control with absolute confidence.
Definition of Git Reset and Git Revert
See also: git undo last commit
To understand git reset and git revert, we must first recognize how Git tracks project evolution. At its core, Git is a directed acyclic graph of snapshots, where each commit points to its parent and represents a complete state of the project. When you need to reverse changes, git reset and git revert offer two divergent paths. Git reset is a powerful tool that rewrites history by moving the current branch pointer (HEAD) backward to a specified commit. In doing so, it effectively un-commits changes, allowing you to drop commits entirely or keep the modifications in your working directory and staging area for further refinement. It alters the timeline of your branch, making it appear as though certain commits never occurred. Git revert, on the other hand, takes a completely non-destructive approach to history management. Instead of altering past commits or moving branch pointers backward, git revert calculates an inverse patch of the target commit and applies it as a brand-new commit on top of your current history. The original erroneous commit remains completely intact in the log, but its practical effects are entirely nullified by the new revert commit. This foundational distinction determines whether a command is safe for public, shared repositories or restricted to local, isolated branches.
How Git Reset Works
See also: mastering git reset --hard
To wield git reset effectively, you must understand its three distinct operational modes, commonly referred to as soft, mixed, and hard. These modes dictate what happens to the changes after the HEAD pointer is moved. When you execute git reset, Git manipulates three primary trees: the HEAD (the current commit snapshot), the Index (the staging area where changes wait before the next commit), and the Working Directory (the actual files you see and edit in your filesystem). Understanding how each mode interacts with these three trees is essential for avoiding accidental data loss.
The soft mode (--soft) is the most conservative variant of git reset. When you run git reset --soft HEAD~1, Git moves the HEAD pointer back by one commit, but it leaves both the Index and the Working Directory completely untouched. This means all the files changed in that undone commit remain safely staged and ready to be committed again. Developers frequently use this mode when they realize they made a minor typo in a commit message, want to combine multiple recent commits into a single cohesive commit via an interactive rebase, or simply want to restructure their most recent changes without losing any staging configuration.
The mixed mode (--mixed) serves as the default behavior when no flag is explicitly provided. Executing git reset HEAD~1 or git reset --mixed HEAD~1 moves the HEAD pointer backward and updates the Index (staging area) to match the target commit, but it leaves the Working Directory entirely alone. Consequently, your modified files remain intact on your disk, but they are now marked as unstaged changes. This gives you the flexibility to inspect the files, modify specific lines, stage portions of the work using interactive staging patches, or discard them altogether.
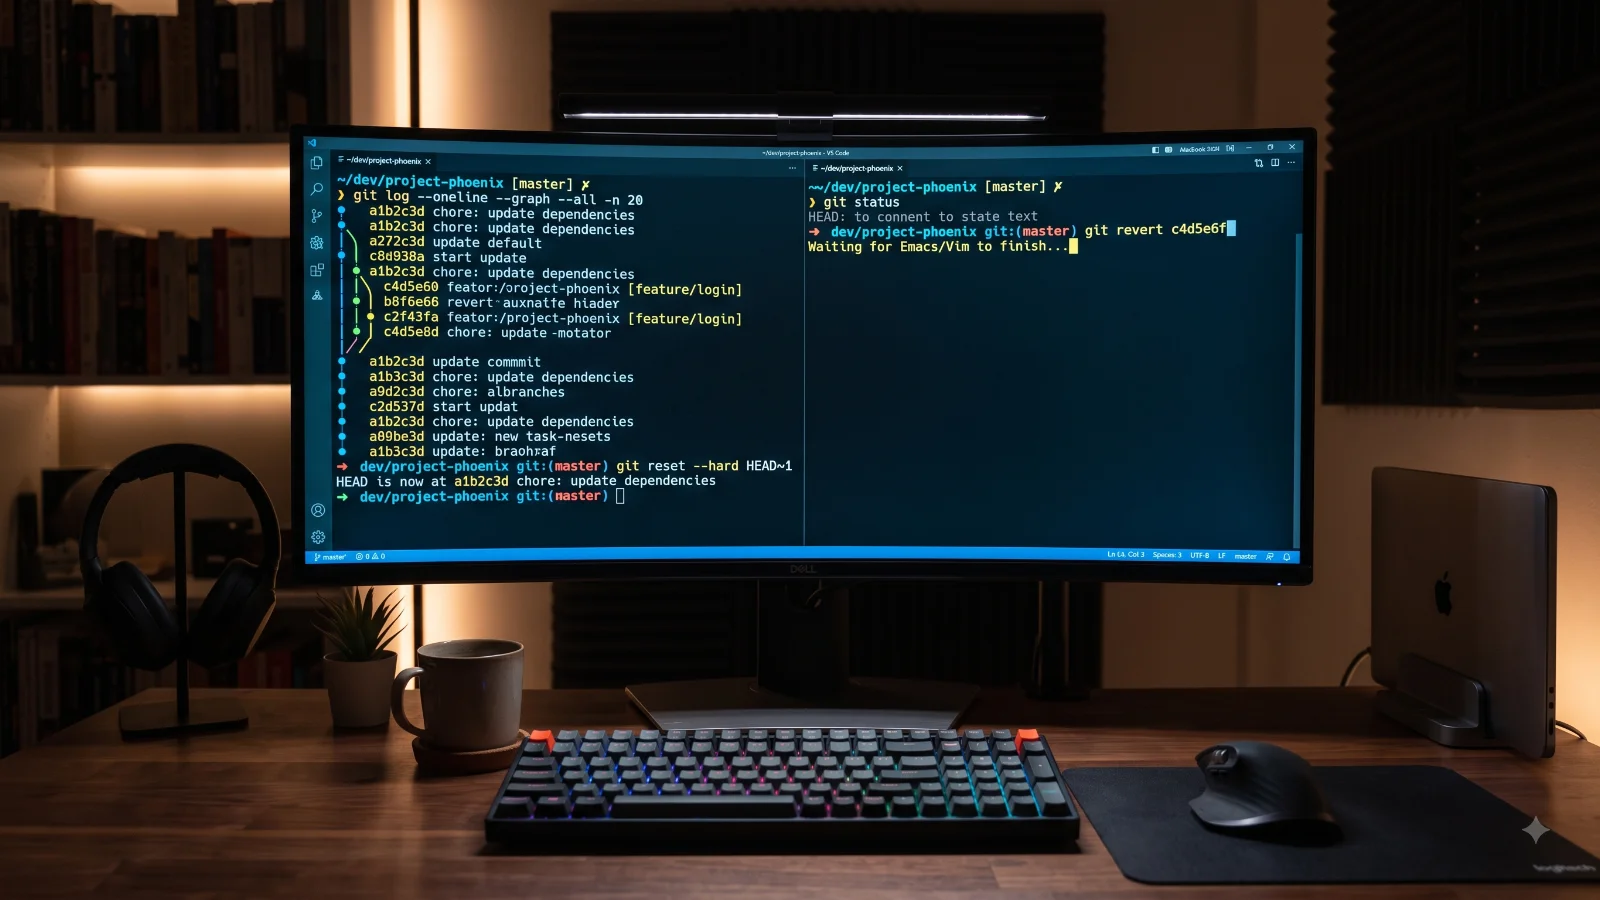
The hard mode (--hard) is the most aggressive and destructive variant of git reset. Running git reset --hard HEAD~1 moves the HEAD pointer, resets the staging area, and completely overwrites the Working Directory to match the specified commit. Any uncommitted changes, untracked files in conflict paths, or modifications made within the undone commits are permanently discarded and vaporized from the filesystem. Because this operation cannot be easily undone once executed, developers must exercise extreme caution when invoking hard resets.
How Git Revert Works
See also: git revert commit
While git reset manipulates history by erasing or shifting past timeline markers, git revert preserves the integrity of the project timeline by moving forward. When you execute a git revert command, Git examines the specified commit, computes the mathematical inverse of the changes introduced in that commit, and applies that inverse patch to your current working tree. It then automatically opens your configured text editor to prompt for a commit message explaining the reversion, and subsequently records a brand-new commit on your current branch. This means the total number of commits in your repository actually increases, rather than decreases.
The mechanics of git revert make it exceptionally safe for collaborative environments. Because no existing commits are modified, deleted, or removed from the commit graph, your local history remains completely aligned with any remote repository where other developers are pulling code. If commit A introduced a bug, and you run git revert A, Git creates commit B, which contains the exact opposite changes of commit A. Anyone inspecting the git log will see both commit A and commit B, providing a clear, transparent audit trail of what went wrong and when it was fixed. This transparency is invaluable during debugging sessions, code reviews, and compliance audits where traceability is paramount.
Key Components and History Impact
Evaluating the impact of git reset versus git revert requires analyzing how they interact with local versus shared remote repositories. In Git terminology, rewriting history refers to modifying commits that have already been pushed to a public remote repository like GitHub, GitLab, or Bitbucket. When you push commits to a shared remote, other developers pull those commits into their own local repositories, establishing them as the foundation for their ongoing work.
If you use git reset locally on your own machine to roll back three commits, your local branch diverges from the remote branch. When you attempt to push your changes, Git rejects the push because your local history has been rewritten and is no longer a linear descendant of the remote history. To force the push, developers sometimes resort to git push --origin main --force. However, force-pushing a shared branch is widely considered a dangerous anti-pattern in collaborative software engineering. When you force-push a reset history, your teammates' local repositories become out of sync. When they attempt to pull or push, their repositories will experience severe divergence, leading to duplicated commits, lost work, and hours of tedious manual conflict resolution.
Git revert completely eliminates this danger. Because git revert never rewrites existing history, but instead adds a new commit to the end of the chain, pushing a reverted commit to a shared remote is entirely safe. It integrates seamlessly into standard pull requests and continuous integration pipelines without disrupting your team. Therefore, the cardinal rule of Git history management is simple: use git reset exclusively for local, un-pushed changes where rewriting history is safe and beneficial, and rely on git revert for any changes that already exist on a shared remote branch.
Practical Examples
To solidify these concepts, let us walk through concrete terminal examples for both commands in typical software development scenarios.
Imagine you are working locally on a feature branch and have just made two hasty commits that contain incomplete code and debugging print statements. You want to undo both commits while keeping your code modifications intact in your working directory so you can organize them properly. You would use a mixed reset:
git reset --mixed HEAD~2
After running this command, your HEAD pointer moves back two commits. The staging area is cleared of those commits, but your files remain modified on your disk. You can now selectively stage individual lines using interactive staging:
git add -p
Once your changes are neatly organized, you can create a single, clean commit:
git commit -m "feat: implement user authentication cleanly"
Now consider a different scenario. You pushed your feature branch to GitHub, and your team merged it into the main production branch. Shortly thereafter, monitoring alerts reveal that a specific commit (a1b2c3d) introduced a memory leak. Because this commit is already live on the shared main branch, running a git reset is strictly forbidden. Instead, you check out the main branch, pull the latest changes, and execute a revert:
git revert a1b2c3d
Git automatically calculates the inverse diff, generates a new commit message explaining the reversion, and commits the fix. You then push this safe, non-destructive reversion to the shared remote repository:
git push origin main
The memory leak is neutralized, the audit trail remains pristine, and your team's local repositories update smoothly without a single merge conflict or force-push warning.
Benefits and Advantages
Each command offers distinct advantages tailored to specific phases of the development lifecycle. The primary advantage of git reset lies in its unparalleled flexibility for local workspace curation. It allows developers to sculpt their commit history before sharing it with the world, turning messy, experimental trial-and-error commits into clean, atomic, professionally structured commit logs. It empowers programmers to experiment fearlessly on local feature branches, knowing they can instantly wipe away mistakes or restructure staging areas with a single command.
Conversely, the primary advantage of git revert is absolute collaborative safety. By respecting the immutability of shared commit history, git revert enables teams to fix production bugs, roll back faulty features, and audit changes across large distributed teams without ever risking data corruption or forcing coworkers to perform complex repository repair operations. It bridges the gap between individual experimentation and team-wide stability, ensuring that history remains an accurate, tamper-evident chronicle of the project's evolution.
Limitations and Risks
Despite their immense utility, both commands carry inherent risks that developers must respect. The most prominent danger associated with git reset is permanent data loss, particularly when utilizing the --hard flag. Executing git reset --hard destroys uncommitted work and abandons commits that may be difficult to recover. While Git's reflog (git reflog) can sometimes rescue dangling commits within a short window, relying on the reflog is stressful and error-prone.
Git revert, while safe for history preservation, introduces its own unique set of challenges during complex merge scenarios. If you attempt to revert a commit that modified files which have since undergone extensive structural changes in subsequent commits, Git may encounter merge conflicts while attempting to apply the inverse patch. Resolving these revert conflicts requires careful manual intervention to ensure that the reversion logic correctly accounts for intervening code evolution without accidentally reintroducing bugs or breaking dependent features.
Frequently Asked Questions
When should I use git reset instead of git revert?
Use git reset when working exclusively on local, un-pushed branches where you need to clean up messy commits, unstage files, or discard experimental changes. Use git revert when the problematic changes have already been pushed to a shared remote repository or merged into a public branch.
Does git revert delete commits?
No, git revert does not delete or modify existing commits. Instead, it calculates the inverse of the target commit and appends a brand-new commit to the end of your branch history, ensuring complete transparency and traceability.
Can I undo a git reset hard?
Yes, within a limited timeframe, you can often recover lost commits after a hard reset by inspecting git reflog to find the SHA-1 hash of the previous HEAD position and resetting back to it. However, uncommitted working directory changes wiped by a hard reset cannot be recovered.
Is it safe to use git reset on a shared repository?
Generally, no. Using git reset on shared branches rewrites history and causes divergence when teammates attempt to push or pull, requiring dangerous force-pushes that can disrupt collaborative workflows.
Conclusion
Mastering the nuances of git reset versus git revert is a hallmark of professional software engineering. Git reset acts as your private editing suite, allowing you to sculpt local history and organize your workspace with surgical precision. Git revert serves as your collaborative safety net, enabling you to undo mistakes on shared branches without disrupting your team. As a reliable rule of thumb: if the code has not left your machine, reset freely; if the code has been pushed to share, always revert.
📌 Recommended Next Guides & References
  <li>
    <a href="/article/docker-and-kubernetes-how-they-work-together-2" class="text-primary hover:underline font-semibold flex items-center gap-2">
      <span>→</span> <span>Docker and Kubernetes: How They Work Together</span>
    </a>
  </li>

  <li>
    <a href="/article/kubernetes-ingress-explained" class="text-primary hover:underline font-semibold flex items-center gap-2">
      <span>→</span> <span>Kubernetes Ingress Explained: Routing, Controllers, and TLS</span>
    </a>
  </li>

  <li>
    <a href="/article/kubernetes-ingress-controller-explained" class="text-primary hover:underline font-semibold flex items-center gap-2">
      <span>→</span> <span>Kubernetes Ingress Controller Explained: Architecture, Routing, and Implementation</span>
    </a>
  </li>